How PaymentKit Handled Our Failed Payments Problem
We tracked failed payments for three months before the pattern became impossible to ignore. Declines clustered around the same card brands and the same days of the billing cycle. Support tickets rose in parallel. Revenue forecasts missed targets by a consistent margin. We decided to measure the gap, isolate the causes, and change the recovery steps rather than keep absorbing the losses.
Mapping the actual failure points
We pulled every declined transaction from the previous quarter and sorted them by decline code, processor, and customer tenure. Soft declines made up the largest share. Hard declines sat lower yet still removed entire accounts when the customer never returned. Timing mattered more than we expected. Cards that failed on the first attempt often succeeded two or three days later when the available balance reset. We listed the exact sequences that repeated and marked which ones our previous process never caught. The spreadsheet showed gaps in both retry timing and customer notification. One mid-size account, for example, failed three times in a row because the retry window closed before the next payroll deposit landed.
Setting recovery rules that matched the data
We configured adaptive retries based on the decline codes that appeared most often. Retry timing varied by decline type, with temporary technical failures and insufficient funds handled through different recovery schedules. Hard declines followed a separate process, prompting customers to update their payment details rather than repeatedly attempting the same card. Email sequences started after the first failed retry and escalated only when the payment remained unpaid. The messages stayed factual and short. We tested the full path in a sandbox with simulated declines before moving any live traffic. We used the recovery options available through Paymentkit.com without requiring custom code for the basic flow. After the test period we activated the rules on a limited segment of renewals.
One failed payment that exposed the old process
A customer on an annual plan hit a soft decline on the renewal date. The previous process logged the failure, sent a single generic email, and waited. Fourteen days later the account still sat unpaid. Support opened a ticket after the customer noticed the service interruption. We reconstructed the timeline. The card had sufficient funds two days after the first attempt. Our old retry never fired again. Under the new sequence the same decline would have retried on day two and day four, then sent a clear update on day five. We applied the corrected path to that account manually and recovered the payment within forty-eight hours. The case confirmed the data we had already collected.
Changing how the team handles open failures
We removed the daily manual check of the decline list. The system now surfaces only the accounts that exhaust the automated path. Support reviews those residual cases once per week instead of every morning. Product no longer receives emergency requests to pause features for unpaid accounts that later resolve themselves. We documented the new handoff points in a short internal note so any team member can follow the same sequence. The volume of open failure tickets dropped within the first billing cycle after the change.
Measuring what actually moved
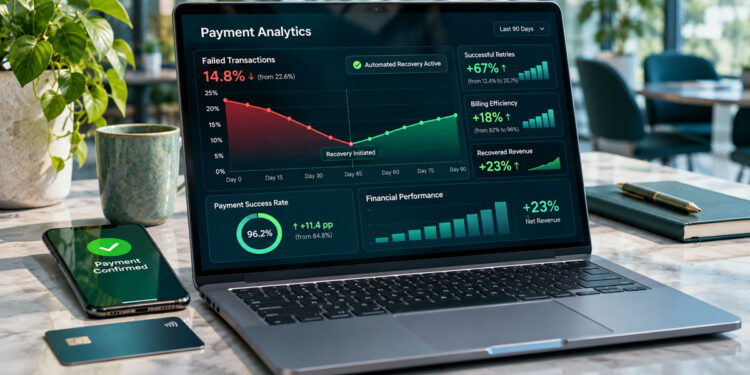
Authorization rates on renewals rose by nine percentage points in the first full month. Recovered revenue from previously failed attempts added a measurable line to the monthly report. The average time from initial decline to successful collection shortened from eleven days to four. Support tickets related to billing interruptions fell by more than half. We tracked these numbers against the same period in the prior year to confirm the difference was not seasonal. The recovery rules continued to improve as more decline data accumulated. We adjusted two interval settings after the second month based on the new distribution of codes.
The residual failures that still require human review now arrive with full context already attached. We spend less time reconstructing histories and more time deciding whether to offer a one-time adjustment or close the account. That shift changed the weekly rhythm more than any single metric. The process no longer depends on one person remembering to open the decline report every morning. It runs whether or not that person is available.
We keep a short log of the original failure patterns next to the current rules. The comparison shows which assumptions we held and which ones the data corrected. Small adjustments still appear every few months when a new card network or region enters the mix. The core sequence stays stable. The measurable gap between decline and recovery continues to narrow.